How it works
You choose a model in VEX Desktop, and VEX runs it for you. You pay in $VEX, from a balance you deposit in the app.
- The hold. Before a request runs, VEX holds the most it could cost. A request can never spend more than your balance.
- The charge. When the model answers, you are charged what the model provider billed, plus the 15% VEX share, converted to VEX at a 60-minute average price (TWAP). If the provider reports no bill, because you stopped the request, the connection dropped or the provider failed mid-answer, you are charged an estimate instead: the input tokens VEX counted and every output token received, at the model's listed prices, plus the VEX share, never more than the hold. A request the provider rejects before it answers costs nothing.
- The release. The rest of the hold returns to your balance at once.
The hold
before it runs
holds its worst case
The charge
billed + the 15% VEX share
charged in VEX at the TWAP
The release
the rest of the hold
released to your balance
Prices
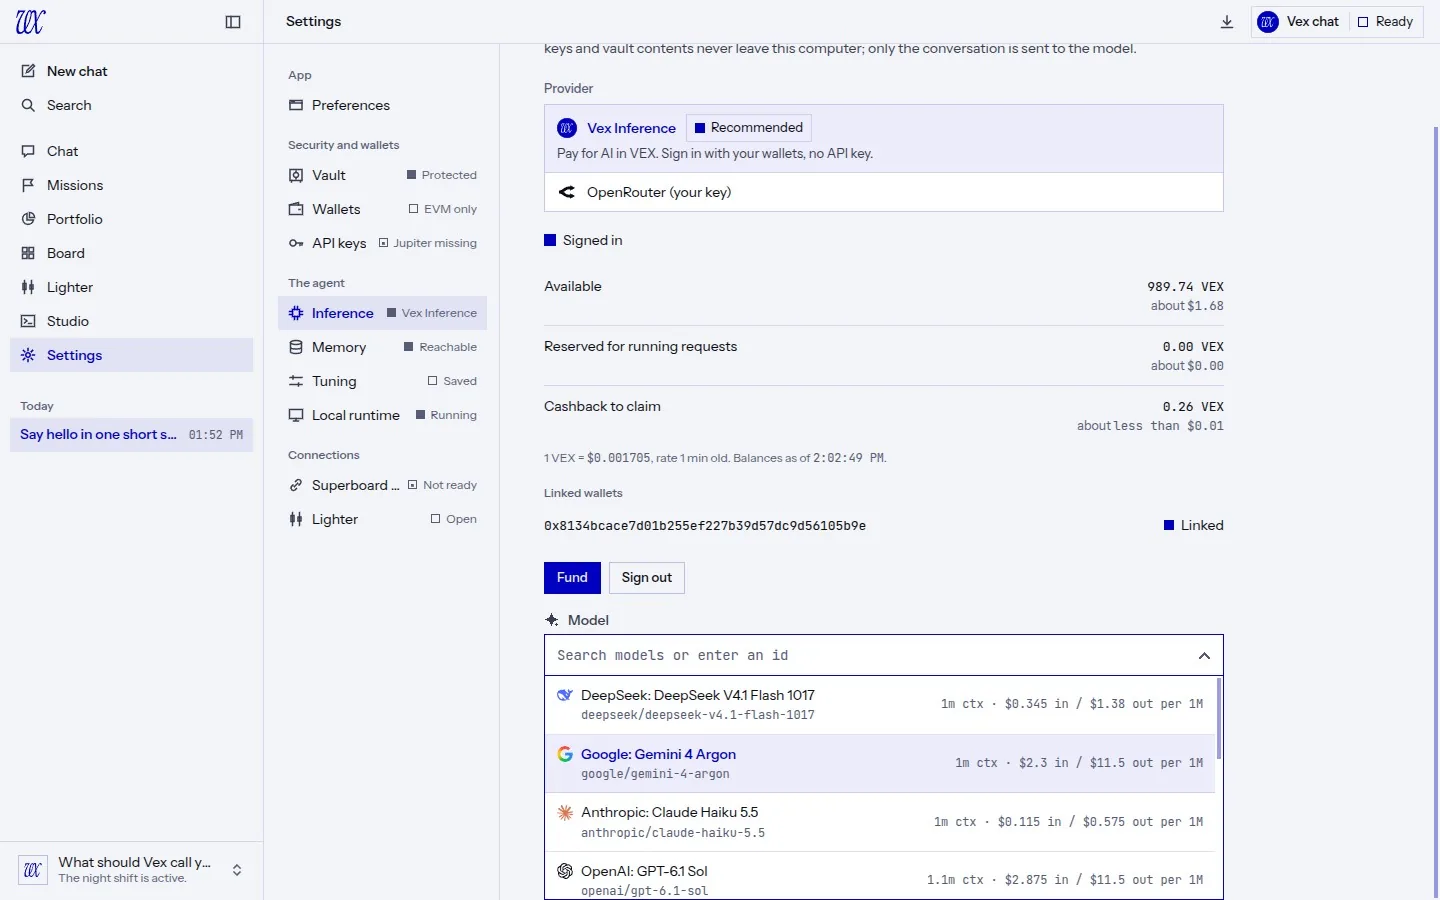
The models and their prices are live at inference.projectvex.ai/v1/models (opens in a new tab). Prices are in USD per 1 million tokens. You pay in VEX, converted at the 60-minute TWAP.
Prices include the 15% VEX share.
Here a token is a piece of text a model reads or writes, not the $VEX token. Input is what the model reads, output what it writes. Cache read is input the provider serves from its cache at a lower price, and cache write is input stored in that cache for the next request.
- Model
- Claude Haiku 5.5
- ID
- anthropic/claude-haiku-5.5
- Context
- 1,000,000
- Input
- 0.115
- Output
- 0.575
- Cache read
- 0.0115
- Cache write
- 0.14375
- Model
- Claude Sonnet 5.5
- ID
- anthropic/claude-sonnet-5.5
- Context
- 1,000,000
- Input
- 2.3
- Output
- 11.5
- Cache read
- 0.115
- Cache write
- 2.875
- Model
- Claude Opus 5.5
- ID
- anthropic/claude-opus-5.5
- Context
- 1,000,000
- Input
- 4.6
- Output
- 23
- Cache read
- 0.23
- Cache write
- 5.75
- Model
- Claude Fable 5.1
- ID
- anthropic/claude-fable-5.1
- Context
- 1,000,000
- Input
- 11.5
- Output
- 57.5
- Cache read
- 0.2875
- Cache write
- 14.375
- Model
- GPT-6 Luna
- ID
- openai/gpt-6-luna
- Context
- 1,050,000
- Input
- 0.14375
- Output
- 0.575
- Cache read
- 0.0115
- Cache write
- 0.14375
- Model
- GPT-6.1 Sol
- ID
- openai/gpt-6.1-sol
- Context
- 1,050,000
- Input
- 2.875
- Output
- 11.5
- Cache read
- 0.115
- Cache write
- 2.875
- Model
- GPT-6 Astra
- ID
- openai/gpt-6-astra
- Context
- 1,050,000
- Input
- 14.375
- Output
- 57.5
- Cache read
- 1.15
- Cache write
- 14.375
- Model
- Gemini 3.8 Flash
- ID
- google/gemini-3.8-flash
- Context
- 1,048,576
- Input
- 0.8625
- Output
- 4.3125
- Cache read
- 0.094875
- Cache write
- Not listed
- Model
- Gemini 4 Argon
- ID
- google/gemini-4-argon
- Context
- 1,048,576
- Input
- 2.3
- Output
- 11.5
- Cache read
- 0.115
- Cache write
- Not listed
- Model
- DeepSeek V4.1 Flash 1017
- ID
- deepseek/deepseek-v4.1-flash-1017
- Context
- 1,048,576
- Input
- 0.345
- Output
- 1.38
- Cache read
- 0.0069
- Cache write
- Not listed
10 of 10 models · read 2026-10-25 15:20 UTC from the live list
What one price line does not show
- Long-context tiers. Above a prompt size, some models bill the whole request at a higher rate: Claude Haiku 5.5 above 100,000 prompt tokens, the GPT-6 models above 272,000. The table shows the base tier, and VEX holds enough for the higher tier whenever your prompt can reach it. A typical agent turn sends about 45,000 prompt tokens.
- Off-peak prices. DeepSeek V4.1 Flash 1017 is priced by time of day. The table shows its peak price (Monday to Friday, 01:00 to 04:00 and 06:00 to 10:00 UTC); at every other hour, and all day on Chinese public holidays, you pay half.
- Promotional prices ending. Google lists both Gemini models at promotional prices: Gemini 4 Argon until 2026-11-30 and Gemini 3.8 Flash until 2026-12-31. You pay what the provider bills plus the VEX share, so a new provider price reaches your charge on its own.
- Gemini cache writes. Gemini has no per-token cache-write price. Implicit caching (what VEX uses) charges no write; Google bills explicit cache storage per hour.
Notes as of 2026-10-22.
The VEX share
Prices include a 15% VEX share, and all of it goes back into VEX.
For every $1 of model cost:
- Part of the VEX share
- Burned as VEX
- Share
- 6%
- Per $1
- 6 cents
- Part of the VEX share
- Cashback to you
- Share
- 3%
- Per $1
- 3 cents
- Part of the VEX share
- The VEX treasury
- Share
- 3%
- Per $1
- 3 cents
- Part of the VEX share
- The VEX to USDG conversion and the compute provider's 2% top-up fee
- Share
- about 3%
- Per $1
- about 3 cents
Burns run in batches; each one is a public transaction. The burned VEX leaves the supply.
The treasury's address: 0xe341f3da256C38356bce4Afd456d7fa36E356E94 (opens in a new tab)
Deposits and withdrawals
Deposits
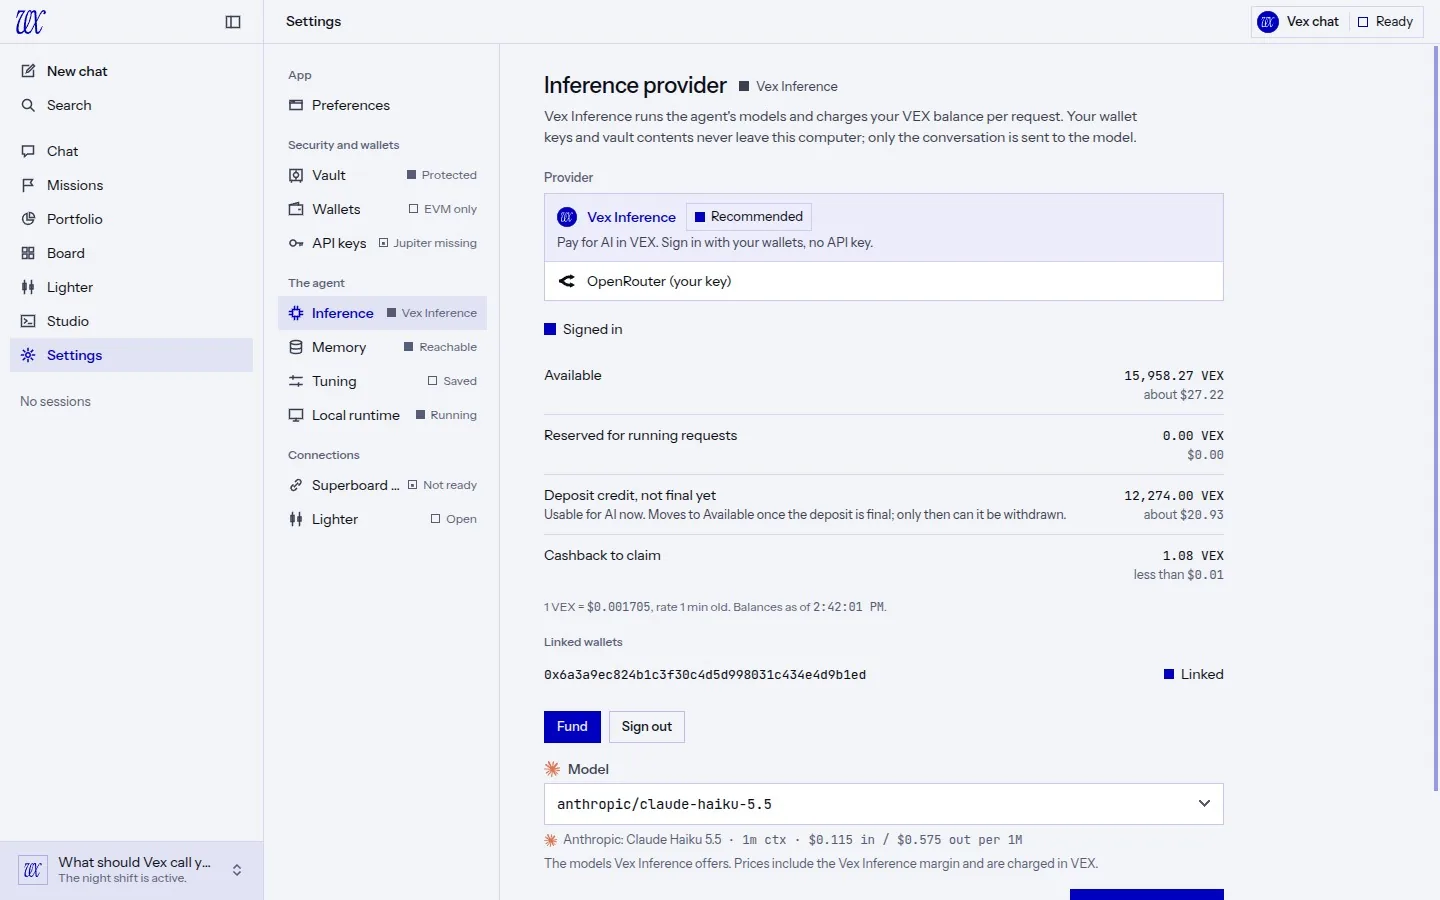
- You deposit VEX from the app.
- Up to $25 of a deposit is usable within seconds, as provisional credit.
- The deposit is final after about 16 minutes on Robinhood Chain.
The deposit address, on Robinhood Chain (chain 4663): 0xf36aed1c11A3140594609969DC6646c9F8a981C5 (opens in a new tab)
Withdrawals
- A withdrawal waits through a 12-hour cooling.
- You can cancel it while it cools.
- It goes only to a wallet linked to your account.
Prompt caching
Prompt caching passes through to you. When a large prompt repeats, the provider's cache prices apply, and the charge follows them.
92 to 97% cheaper on a repeated large prompt, measured 2026-10-22
Claude models need an explicit cache breakpoint, and VEX Desktop sends one. OpenAI models cache automatically.
Measured performance
Measured on 2026-10-22, from Poland to the gateway in Azure Central US. The gateway's own time is what VEX adds to a request before the model starts; the model's time and the network path are not in it.
30 to 40 ms the gateway's own time per request, median
about 2 ms auth, median
28 to 38 ms admission, median per model
0 unexplained billing mismatches in 1,403 checked charges
Method: one campaign of paired requests per model, timed from each response's Server-Timing header. Of the 1,403 checked charges, 1,378 were compared with the cost the provider billed. The other 25 were requests that failed without a bill from the provider; each was charged an estimate and checked as one.